—AI Implementation
The Benchmark Illusion: Why Top-Scoring AI Agents Only Succeed 30–40% of the Time on Real Enterprise Work
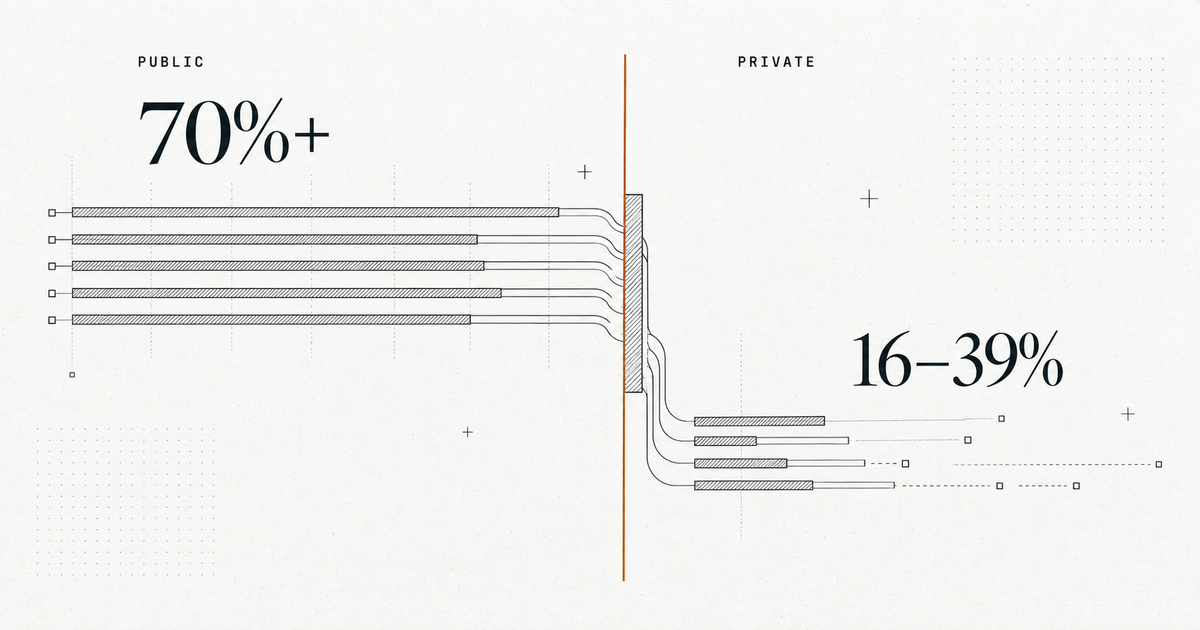
On public leaderboards, the top AI agents post ever-more-impressive scores. Plug one into your own private systems, though, and the success rate often collapses to somewhere between 30% and 40%. This piece uses three primary benchmarks from this week — a 38.8% pass@1 on real private enterprise code, a consistency gap that drops success from 77.4% to 53.0%, and a 73.4% failure rate on long tasks — to break down the three layers of the "dazzling demo, broken deployment" gap, and to explain why supplying private context, not chasing a higher leaderboard score, is the real lever for getting agents into production.
September 22, 2026·9 min read
Read more→
 6AM TECH